跳到正文 / Skip to content

论文Publications

按研究领域分组。* 表示共同一作。Grouped by research area. * indicates equal contribution.

生成式 AI 与图像/视频生成Generative AI · Image & Video Generation

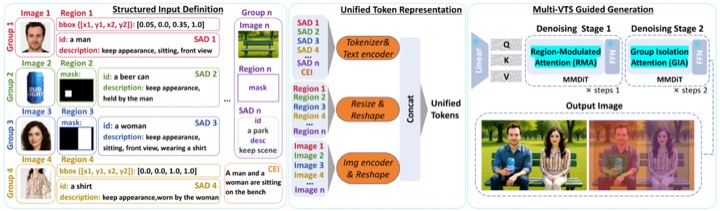
论文方法示意图:LAMIC:基于多模态扩散 Transformer 可扩展性的布局感知多图合成
研究简介:动机、方法与发现 Research summary: motivation, method, findings
研究动机Motivation

单图参考扩散模型很难同时整合多个主体与明确空间布局。Single-reference diffusion models struggle to compose multiple entities under explicit spatial layouts.

核心方法Approach

无需训练,利用 Group Isolation Attention 和 Region-Modulated Attention 扩展 MMDiT 的多参考组合能力。Training-free multi-reference composition with Group Isolation Attention and Region-Modulated Attention on MMDiT.

主要发现Findings

在论文所用的多图组合基准上改善身份保持、背景一致性与区域布局控制。Reported gains in identity preservation, background consistency, and layout control on the evaluated composition benchmarks.

局限与边界Limitations

这些结果属于所测试的生成模型与基准;不能推断任意架构或复杂场景都同样有效。Findings depend on the evaluated models and benchmarks; they do not establish universal robustness.

核对依据:Summary source: AAAI 2026 官方摘要 ↗ AAAI 2026 proceedings abstract ↗
AI 安全与信息隐藏AI Safety & Information Hiding

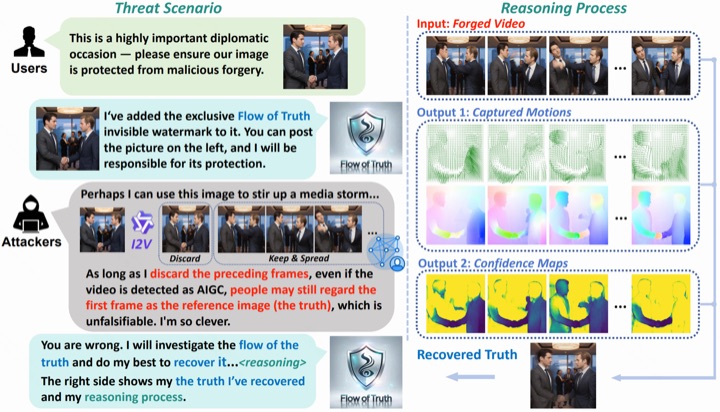
论文方法示意图:Flow of Truth:面向图像到视频生成的主动式时序取证
研究简介:动机、方法与发现 Research summary: motivation, method, findings
研究动机Motivation

图生视频生成会让图像取证痕迹随时间漂移,单帧检测难以追踪变化。Image-to-video synthesis moves forensic evidence over time, complicating frame-only detection.

核心方法Approach

把生成过程表述为像素随时间的运动,构建可学习的跟踪模板与模板引导的运动模块。Treats video generation as pixel motion over time using a learnable forensic template and template-guided flow.

主要发现Findings

论文报告了跨开放及商用 I2V 模型的时序取证泛化实验。The paper reports temporal-forensics results on commercial and open I2V generators.

局限与边界Limitations

目前属于公开预印本;实验结论应按文中数据与生成设置理解。This is a public preprint; conclusions are bounded by the evaluated models and settings.

核对依据:Summary source: arXiv 预印本摘要 ↗ arXiv preprint abstract ↗

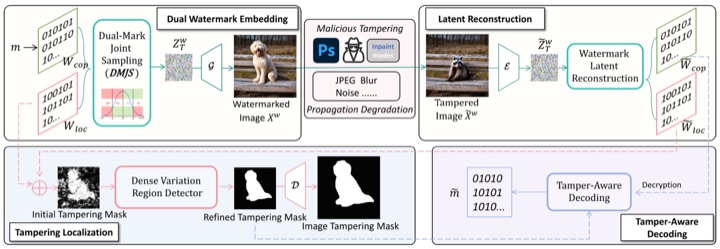
论文方法示意图:TAG-WM:基于扩散反演敏感性的篡改感知生成图像水印
研究简介:动机、方法与发现 Research summary: motivation, method, findings
研究动机Motivation

生成图片需要同时证明来源与定位后续恶意编辑,单一稳健水印难以兼顾两者。Generated images need both provenance verification and post-edit tamper localization.

核心方法Approach

联合嵌入版权与定位水印,再通过扩散反演敏感性识别被篡改区域。Combines copyright/localization watermarking with diffusion inversion sensitivity for tamper localization.

主要发现Findings

论文在图像质量、抗失真与定位能力方面报告了多项实验。The ICCV paper reports robustness, localization, and image-quality evaluations.

局限与边界Limitations

水印的适用性需结合具体生成与编辑模型、威胁模型评估。Performance must be interpreted under the tested generators, edits, and threat assumptions.

核对依据:Summary source: ICCV 2025 官方摘要 ↗ ICCV 2025 open-access abstract ↗

科研生态与同行评审Meta-Science & Peer Review

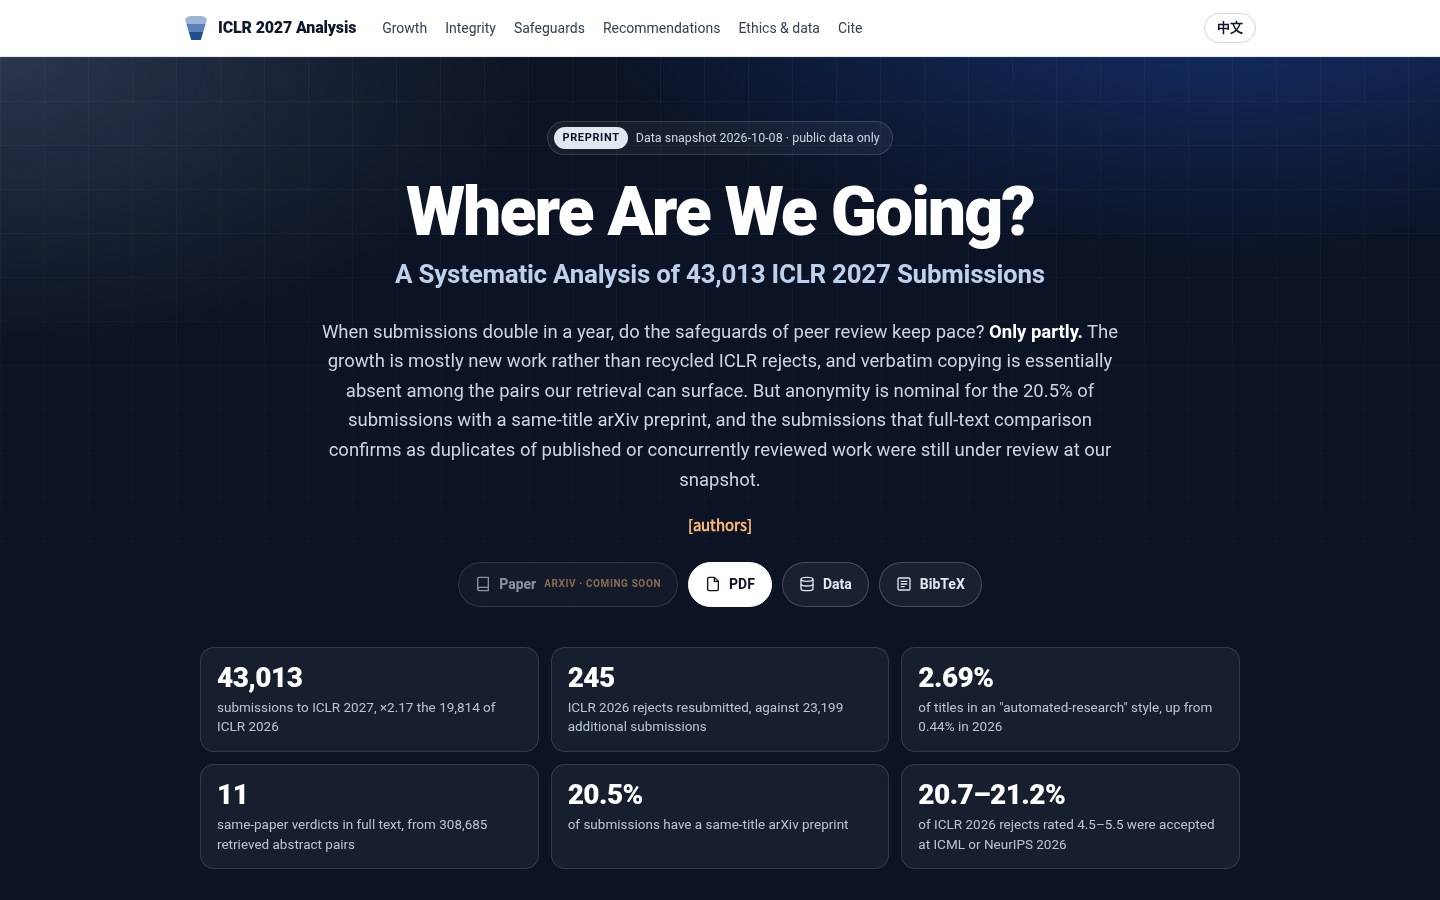
论文方法示意图:我们将走向何方?对 43,013 篇 ICLR 2027 投稿的系统分析
研究简介:动机、方法与发现 Research summary: motivation, method, findings
研究动机Motivation

面对投稿规模变化,需要可核对的学术数据了解研究热点与审稿生态。Changes in submission scale motivate an auditable overview of research trends and peer-review workload.

核心方法Approach

以 2026-10-08 的公开投稿快照为基础,开展主题分布、重复论文筛查及同行评审相关描述性分析。Descriptive analysis of the public 2026-10-08 ICLR 2027 submission snapshot, including topics and overlap audits.

主要发现Findings

研究页面报告覆盖 43,013 篇投稿的描述性统计。The analysis reports descriptive statistics over 43,013 submissions.

局限与边界Limitations

这是投稿分布的描述性研究,不等于最终录用趋势或论文质量的因果证据。Submission statistics cannot establish final acceptance patterns or causal paper-quality claims.

核对依据:Summary source: 公开分析页面及数据快照 ↗ Public analysis and data snapshot ↗

AI + 医疗AI for Medicine

研究简介:动机、方法与发现 Research summary: motivation, method, findings
研究动机Motivation

单用白细胞图像的高层语义,可能丢失诊断相关的形态信息。WBC classifiers may overlook diagnostically useful morphology when emphasizing high-level features.

核心方法Approach

使用双分支、双注意力特征融合,结合形态属性提取,并通过深度监督和半监督策略改进相关模块训练。Dual-branch fusion of morphological and semantic features, with deep-supervised and semi-supervised learning strategies.

主要发现Findings

论文在六个公开白细胞图像数据集上分别报告分类准确率;这些指标不能直接跨临床条件外推。The paper reports accuracy on six public WBC image datasets, not clinical diagnostic outcomes.

局限与边界Limitations

离线图像分类精度不能直接视作真实临床诊断表现。Image-classification benchmarks do not alone establish clinical effectiveness.

核对依据:Summary source: Biomedical Signal Processing and Control 出版摘要 ↗ Biomedical Signal Processing and Control abstract ↗

CMPB

基于高光谱成像与 Transformer 的肾小球疾病精准分类 Accurate classification of glomerular diseases by hyperspectral imaging and transformer

Chongxuan Tian, Yuzhuo Chen, Yelin Liu, Xin Wang, Qize Lv, Yunze Li, Jinlin Deng, Yifei Liu, Wei Li

研究简介:动机、方法与发现 Research summary: motivation, method, findings
研究动机Motivation

肾小球病理分类需要联合利用组织图像的空间结构与光谱信息。Glomerular classification can benefit from integrating spatial structures and hyperspectral signals.

核心方法Approach

结合卷积网络与 Vision Transformer,融合高光谱的空间和波段特征。Combines CNN and Vision Transformer features from hyperspectral spatial/spectral signals.

主要发现Findings

论文报告其数据设置下 CVT 的平均分类准确率为 94%;仅用光谱特征的模型为 85.24%。The paper reports 94% mean accuracy for CVT versus 85.24% for the spectral-only model in its study.

局限与边界Limitations

小样本病理分类实验不等价于多中心临床验证。Small-sample classification results do not constitute multicenter clinical validation.

核对依据:Summary source: PubMed 摘要 ↗ PubMed abstract ↗