AAAI 2026
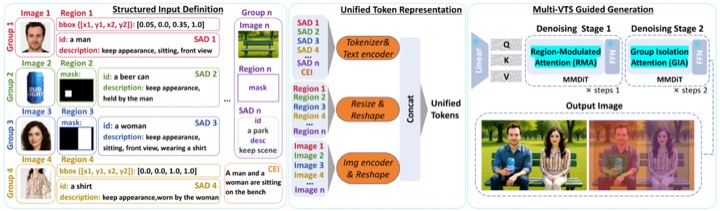
LAMIC: Layout-Aware Multi-Image Composition via Scalability of Multimodal Diffusion Transformer
LAMIC:基于多模态扩散 Transformer 可扩展性的布局感知多图合成LAMIC: Layout-Aware Multi-Image Composition via Scalability of Multimodal Diffusion Transformer
你好,我是Hi, I'm
让 AI 理解、生成,并与世界交互Teaching AI to understand, generate, and interact with the world
兴趣:多模态生成 · 多模态理解 · 机器人 · 仿真 · 游戏 · 强化学习Interests: multimodal generation · multimodal understanding · robotics · simulation · games · RL
📍 中国科学技术大学(USTC) · 中国·合肥 📍 University of Science and Technology of China (USTC) · Hefei, China
LAMIC:基于多模态扩散 Transformer 可扩展性的布局感知多图合成LAMIC: Layout-Aware Multi-Image Composition via Scalability of Multimodal Diffusion Transformer
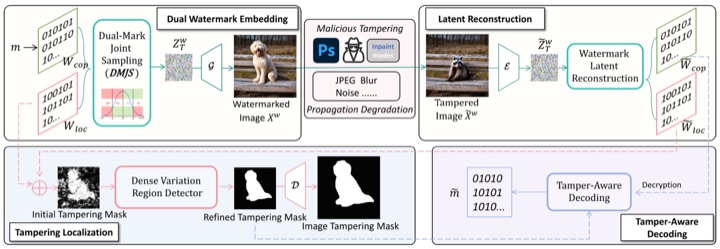
TAG-WM:基于扩散反演敏感性的篡改感知生成图像水印TAG-WM: Tamper-Aware Generative Image Watermarking via Diffusion Inversion Sensitivity
记录持续感兴趣的技术路线与研究疑问:认真阅读已有工作,也区分个人判断和经过验证的结论。Technical interests and open questions, separating the literature, hypotheses, and personal perspectives.
INTEREST · 技术路线INTEREST · Technical survey
为什么自适应推理影响 Agent 的固定预算有效产出与机器人在线时延?梳理 SFT、成本敏感 RL、步骤级信用分配、反应—规划切换的最新研究;区分真正学会思考时机与仅减少 CoT,并讨论有限推理机会能否促进参数化直觉的待验证假设。A critical survey of SFT, cost-aware RL, reasoning credit assignment, adaptive planning and robot latency. Tests the distinction between shorter CoT and genuinely learned, transferable parametric intuition.
阅读技术路线与个人思考 →Read the survey and perspective →INTEREST · 技术路线INTEREST · Technical survey
从模型 Token、API 结构化输出到 Harness 的工具执行和状态回传,比较 Claude Messages、OpenAI Responses/Codex、Qwen/vLLM、OpenHands、LangGraph、smolagents 与 OpenCode;解释 Thinking、Tool Call、执行反馈和跨轮历史分别由谁负责。An end-to-end comparison of how Claude, OpenAI Responses/Codex, Qwen/vLLM, OpenHands, LangGraph, smolagents and OpenCode organize reasoning, tool use, execution feedback and conversation state.
阅读技术路线与个人思考 →Read the survey and perspective →OPEN QUESTION · 机器人学习OPEN QUESTION · Robot Learning
普通语言 Tokenizer 不保证相近数值有相近表示;VLM 的连续视觉特征也不等于坐标输出具备连续性,而离散 Action Codebook 同样可能扭曲物理邻近关系。对照 xVal、BitTokens、Pix2Seq、FAST、X-Tokenizer、ActionPiece、ProAct 和连续动作头,提出几种可验证的改进路径。Text tokenization does not inherently preserve numerical distance. Continuous visual features do not guarantee metric output continuity, and discrete VLA action codes may distort physical neighborhoods. Review numerical encodings, action codecs, continuous heads, and testable research directions.
查看文献和可验证实验 →Explore evidence and experiments →文献综述 · 术语 · 学习路线 · 研究问题Surveys, concepts, reading paths, questions
公开论文与学术成果Published papers and scholarly work
研究实现、开源工具与演示Research implementations and open-source tools
技术解释、研究随笔与教程Explanations, research notes, tutorials
了解我的研究与实习经历Explore my research and internship experience
查看经历 →View experience →我是中国科学技术大学网络空间安全学院的二年级硕士研究生, 导师为张卫明教授与俞能海教授。 此前在山东大学控制科学与工程学院获得学士学位。我的研究聚焦于人工智能、计算机视觉与安全的交叉领域。
欢迎交流研究思路、开源工具和潜在合作。如果有共同感兴趣的问题,欢迎通过邮件联系。
I am a second-year M.S. student at the School of Cyber Science and Technology, University of Science and Technology of China (USTC), advised by Prof. Weiming Zhang and Prof. Nenghai Yu. Previously I received my B.S. from Shandong University. My research lies at the intersection of AI, computer vision, and security.
I'm happy to discuss research questions, open-source tools, and potential collaborations. Feel free to reach out by email.